

Use the DeepSeek API when you want to build an app or automation without running the model yourself. Run DeepSeek locally when offline access, control over your files, or a fixed model version matters enough to justify managing the software and hardware. For occasional development work, the API is usually the easier starting point; for an offline assistant on a computer you already own, a smaller local model can make more sense.
The important catch is that you may be comparing different models. A small DeepSeek R1 download on your laptop is not the same model as the current hosted Flash or Pro service. A useful decision weighs the quality your task needs, the data you can send, and the total cost of getting a usable result.
If you just want to ask questions in a browser, official DeepSeek Chat is a separate option. You do not need to build an API integration or install model files for ordinary chat. This guide is for choosing where the model runs.
Table of Contents
DeepSeek local vs API: the practical differences
With the official API, your application sends a request to DeepSeek’s servers and receives an answer. With local inference, the model runs on your own computer. Self-hosting uses the same general principle as local inference, but can mean operating a shared server or renting GPU machines in a data center.
A self-hosted model can still have an API. “Local vs API” is shorthand here for running the model yourself versus using DeepSeek’s managed service. The interface alone does not tell you who handles the data.
| Decision | Official DeepSeek API | Local or self-hosted model |
|---|---|---|
| Getting started | Create a key, fund the account if needed, and connect an application. No local GPU required. | Choose a compatible model and runtime, download the files, and allow enough memory to run them. |
| Model choice | Choose from the provider’s current hosted catalog. | Choose an available checkpoint, size, and supported format; keep a particular version if needed. |
| Data and connectivity | Requests leave your application for a hosted service; internet access is required. | Offline use is possible with a fully local setup. Remote tools and cloud services can change that. |
| Cost | Usage charges for input and output, plus your application’s own costs. | Hardware or rental, electricity, storage, and operating time, even when there is no model-provider token bill. |
| Capacity | The provider runs inference; your app still handles account limits, failures, and spending. | Your available memory and compute set the capacity. Shared deployments also need scheduling and access controls. |
| Features | Use the documented features of the selected hosted model and endpoint. | Features depend on the checkpoint, runtime, chat template, and application around it. |
| Maintenance | Maintain your integration and adapt to service changes. | Maintain model files, runtime versions, hardware, security, and recovery. |
For a small app with approved, non-sensitive inputs, the API removes a substantial amount of setup. For work that must continue without an internet connection, it cannot replace a local model. Those two constraints often settle the choice before a detailed cost comparison is necessary.
Start with the model you can actually run
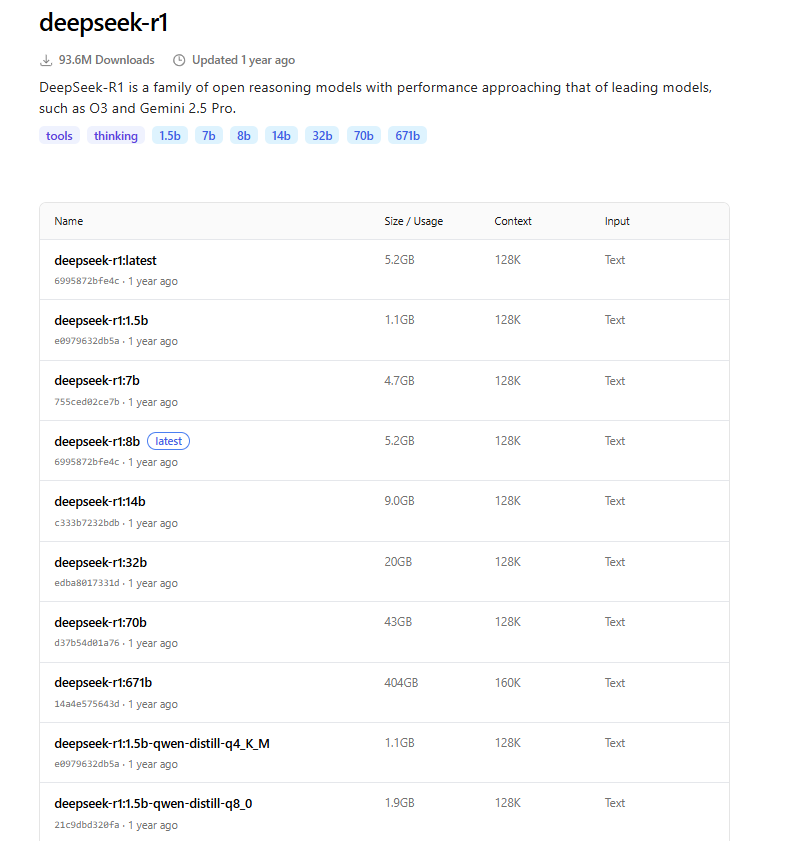
Local DeepSeek covers a wide range of downloads. The original DeepSeek R1 release includes the full reasoning model and smaller distilled models based on Qwen and Llama. Distillation trains a smaller model using material produced by a larger one. Quantization is different: it stores model weights at lower precision to reduce their size. A model can be both distilled and quantized.
That distinction matters when someone says they “run DeepSeek on a laptop.” They may be using a compact, quantized model with different capabilities from the full release. It can still be useful for rewriting notes, explaining short code snippets, or learning how local AI works. It is not evidence that the full hosted model will fit on the same machine or give the same answers.
A realistic local starting point
As a concrete example, Ollama’s deepseek-r1:8b listing currently identifies a Qwen3-based R1-0528 distilled model, using Q4_K_M quantization, with a 5.2 GB download. That is a model-file size, not a 5.2 GB total memory requirement. The operating system, runtime, conversation context, and other applications need room as well.
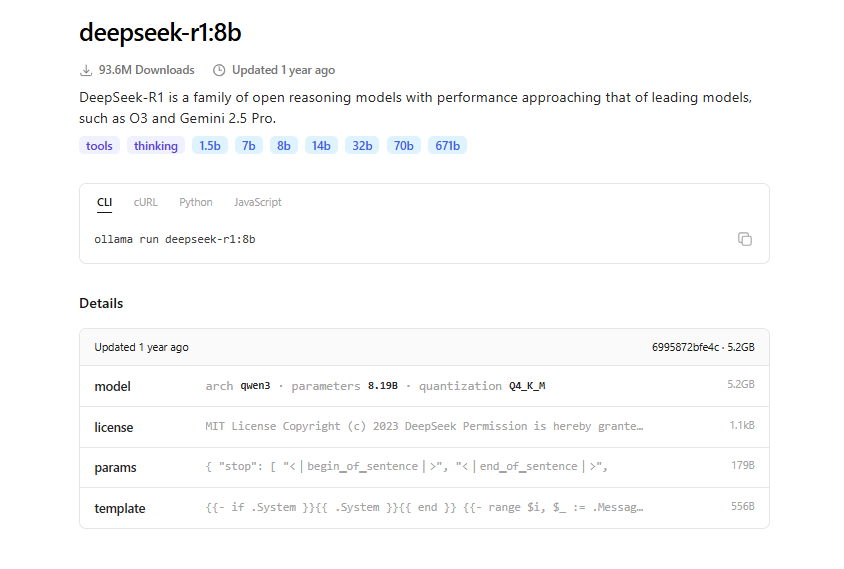
Before downloading, check available system RAM, GPU memory if you have a dedicated card, and free disk space. On machines with unified memory, the model shares that memory with the rest of the system. A supported CPU path may let you run a model without a dedicated GPU, but “it loads” and “it responds comfortably” are different goals.
Start with a modest context length and one conversation. Ollama’s context documentation explains that increasing the context uses more memory. If your intended task is a short paragraph, allocating space for a huge document creates a burden without helping the task. If long documents are essential, choose hardware and a model around that need from the start.
Our DeepSeek system requirements guide covers practical sizing and an initial setup. Use it to narrow the download, then check the exact model’s runtime support before treating a memory estimate as a buying decision.
Full V4 models are a different deployment project
The official V4 Pro model card lists 1.6 trillion total parameters, with 49 billion activated per token. V4.1 Flash lists 763 billion parameters overall, including a 552-billion-parameter backbone, and different active counts during input processing and generation. These are large model deployments, even though only part of the network is active for each token.
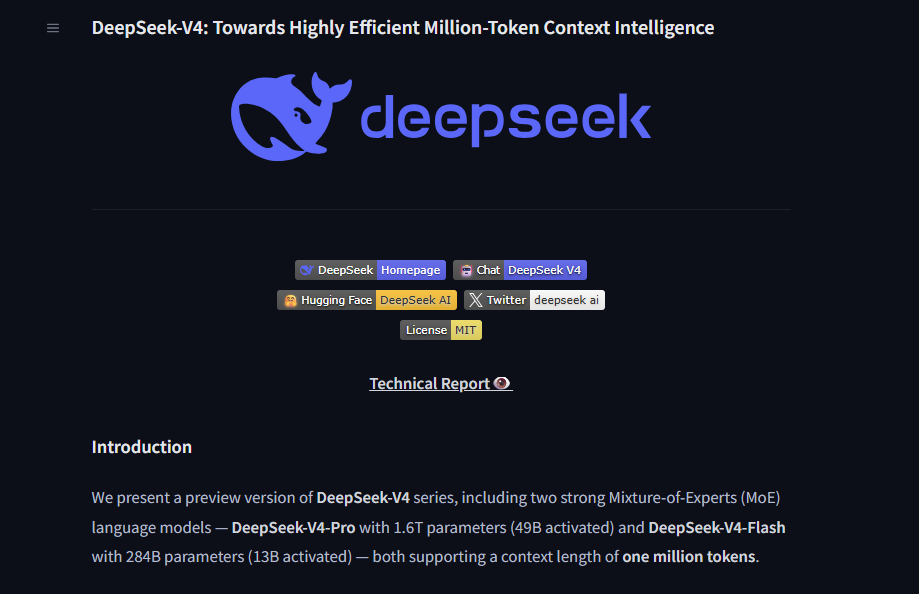
Active parameters describe computation; they are not a shortcut to the memory required to store the model. Weight format, offloading, context, and serving configuration all matter. A GPU recommendation for one checkpoint or precision is not a universal minimum for the whole family.
For most readers considering a normal laptop or workstation, the realistic local comparison is a smaller model. If you specifically need a full V4 checkpoint, plan from its official inference instructions and the serving engine’s support. Do not buy hardware on the assumption that a small active-parameter count means a small download.
Both linked V4 repositories identify their weights as MIT licensed. Other downloads may have different underlying terms, especially derivatives. Check the exact checkpoint and any base-model requirements before redistribution or commercial deployment.
Which is cheaper: local DeepSeek or the API?
The API has a visible usage bill. Local inference spreads its costs across equipment, power, and time. If you already own a suitable computer and use it occasionally, the additional cash cost of a small local model can be low. Buying equipment solely to avoid a small monthly API bill is a different calculation.
Current API rates and a monthly example
The following USD rates were checked against DeepSeek’s official pricing on October 9, 2026. All figures are per one million tokens. Flash means deepseek-flash, currently V4.1-Flash; Pro means deepseek-v4-pro, currently V4-Pro-0813.
| Model and period | Cached input | Uncached input | Output |
|---|---|---|---|
| Flash — peak | $0.006 | $0.30 | $1.20 |
| Flash — off-peak | $0.003 | $0.15 | $0.60 |
| Pro — peak | $0.044 | $1.32 | $3.96 |
| Pro — off-peak | $0.022 | $0.66 | $1.98 |
Peak hours are 01:00–04:00 and 06:00–10:00 UTC, Monday through Friday, excluding Chinese public holidays. Other hours, including weekends and those holidays, are off-peak. These are usage rates, not a monthly subscription; another hosting provider can charge differently.
Consider an illustrative month of 10,000 requests, each using 2,000 input tokens and 500 billed output tokens. That is 20 million input tokens and 5 million output tokens. Assume no cache hits, no retries, no extra tool charges, and that every request is billed at the same peak or off-peak rate.
With Flash at peak rates, the model-token cost is (20 × $0.30) + (5 × $1.20) = $12.00. At off-peak rates it is $6.00. The same token totals cost $46.20 with Pro at peak rates or $23.10 off-peak. These are calculations from stated assumptions, not observed bills or a claim that both models produce identical answers.
The output allowance in that example must cover all billed output, including reasoning tokens when applicable. The official response reference reports reasoning tokens within the completion-token breakdown. A thinking task that generates much more than 500 tokens does not fit the example. Repeated attempts, longer conversation history, and tools that add more requests can also raise the total.
Caching changes the comparison
DeepSeek’s context cache is enabled by default. Reusing a matching, persisted prefix can move some input tokens to the cheaper cache-hit rate. This is useful when requests repeatedly include the same instructions or reference material, but a similar topic does not guarantee a hit.
If half of the example’s 20 million input tokens actually hit the cache, Flash’s peak model-token cost becomes (10 × $0.30) + (10 × $0.006) + (5 × $1.20) = $9.06. The output charge stays the same. Use reported cache-hit and cache-miss usage when estimating an existing workload; do not assume a fixed saving for every application.
For the broader billing details, including payment and other service charges, see our DeepSeek pricing guide. Recheck the official rate table before committing to an infrastructure purchase.
Count the local costs you would otherwise overlook
For a purchased machine, a planning estimate can include the portion of the purchase allocated to AI, spread over the months you expect to use it, plus electricity, storage, and maintenance. This is a budgeting method, not a tax depreciation rule. If the machine already serves other purposes, decide what share belongs to this workload.
For example, assume an entirely hypothetical $2,000 machine allocated over 36 months, plus 100 hours of use at an average 150 watts and electricity at $0.20 per kWh. The monthly allocation is $55.56, and the stated power use adds $3.00, making $58.56 before maintenance and other costs. The price, power draw, and electricity rate are assumptions, not a recommended hardware configuration or a regional tariff.
This does not prove that a $2,000 computer can replace the API workload above. You would first need a local model that meets your quality and speed requirements. It shows why “no token charges” is different from “no cost.” Conversely, if you already own suitable hardware, the purchase may not be a new cash expense, so your decision can reasonably come out differently.
For rented GPUs, count the complete deployment’s hourly price multiplied by the hours it remains allocated, then add storage and other billed services. An idle instance can still cost money. High, steady utilization can improve the economics; short bursts with long idle periods can make a token-priced service easier to justify.
There is no reliable universal request count at which self-hosting wins. Compare the cost per completed, acceptable task, including retries and operator time. A cheaper token is not a saving if the model repeatedly needs correction, and a large server is not economical merely because it can generate many tokens under ideal conditions.
Privacy: follow the data, not the app’s appearance
A desktop chat window can connect to a hosted model. A local web page can send requests to a cloud API. To know where your information goes, identify the model endpoint and the services used for files, search, embeddings, logs, and tools.
What changes with the official API
Using the hosted API sends the request to DeepSeek for processing. Your application can also create its own copies in logs, analytics, or error reports. Before sending confidential material, establish whether the service and those other destinations are approved for that information.
The Open Platform terms specifically cover developers using the API. They place responsibilities on developers for their downstream applications and user-data handling. The general privacy policy also distinguishes the developer’s handling of downstream end-user data from the activities it covers. A statement about consumer chat is therefore not enough to describe every part of your application’s data flow.
If your decision depends on retention, training use, processing location, or a contractual restriction, obtain confirmation for the API service and agreement you will use. Do not infer a zero-retention arrangement from an API endpoint, or assume that self-hosting alone settles every organizational requirement.
What changes with a genuinely local setup
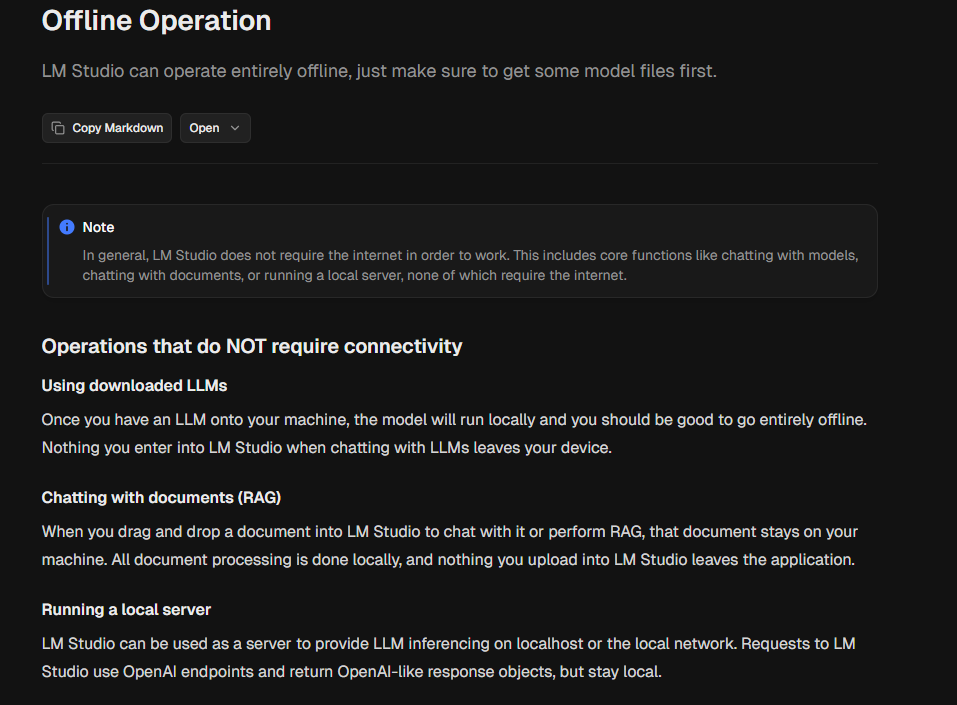
With downloaded weights and local inference, the prompt does not need to go to DeepSeek’s hosted service. LM Studio documents offline operation for downloaded models, local document processing, and its local server. Model discovery, downloads, and other online functions still need connectivity.
Ollama likewise distinguishes local inference from its cloud features. Its FAQ documents a local-only setting that disables cloud models and web search. That is useful when you deliberately want an offline route, but review the rest of your application too: a connected search tool, remote embedding service, or synced conversation folder can still move information elsewhere.
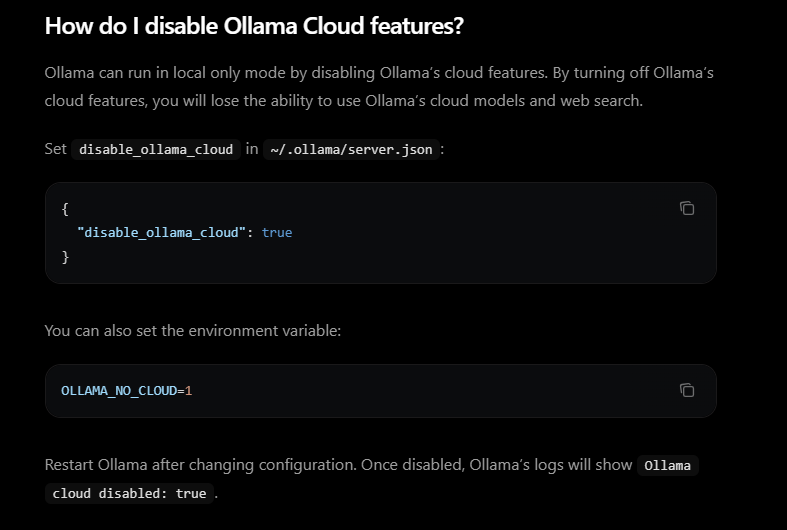
For an offline notes assistant, keep the model, document processing, and any retrieval index on the machine. Download what the setup needs before disconnecting. Confirm that the intended workflow can still complete without a remote tool, rather than assuming that the word “local” covers every component.
Protect the resulting files and history with the same care as the original documents. A shared computer account or an exposed local server can undermine an otherwise private setup. Renting a GPU gives you control over the inference software, but also introduces the hosting provider and its access, storage, and backup arrangements.
Will local DeepSeek give the same quality and features?
Not automatically. Compare the exact checkpoint and task, not just the DeepSeek name. A smaller distilled model, a quantized copy of a larger model, and a current hosted release are different candidates. Their language ability, reasoning, context handling, and formatting reliability can differ.
This affects ordinary work as much as technical tasks. A local model that rewrites a short note well may still struggle with a long document or a multi-file coding request. If you need a specific capability, make that a requirement before choosing the cheapest or easiest download.
Context, images, and tools need separate checks
The current hosted catalog lists a 1M-token context and a general maximum output of 384K for both Flash and Pro. These are service limits, not a promise that every endpoint uses the same limit or that a local runtime will allocate that much context. Endpoint-specific restrictions still apply.
Flash supports image input and returns text; Pro is text-only. JSON output, tool calls, thinking modes, and supported API formats are documented service features. A local runtime needs corresponding support in the checkpoint, template, and request handling. Downloading weights does not automatically reproduce the hosted product around them.
For example, a model can suggest a tool call without executing it. Your application must validate the arguments, decide whether the action is allowed, run the tool, and return its result. The same distinction applies to a local assistant: access to your files comes from the surrounding software and permissions, not from the model name.
Compatibility helps migration, but is not a guarantee
DeepSeek offers an OpenAI-format base URL at https://api.deepseek.com and Anthropic-format access at https://api.deepseek.com/anthropic. Local runtimes can also expose compatible endpoints. This can reduce integration changes, but it does not make all request fields, streaming events, image formats, or error responses interchangeable.
Keep the endpoint, model identifier, and supported features together in your configuration. deepseek-flash is a hosted API ID; deepseek-r1:8b is an Ollama tag. Use the identifier for the server you are actually calling. Older API names and repository names should not be copied into a new integration without checking that server’s documentation.
When judging whether a route fits, choose a few ordinary tasks you need it to perform: extract fields from a sample document, explain a bug, or revise a paragraph while preserving its facts. Define what a correct result looks like and how much correction you can accept. This keeps the choice tied to work you actually need done.
Speed, reliability, and maintenance
Local inference removes the network trip to a hosted model, but that alone does not make it faster. Loading the model, processing the prompt, generating the answer, and waiting behind other requests can take longer than the network time you saved. A model that spills into slower memory may be usable for patient offline work and frustrating for an interactive app.
The API adds network and provider dependence. Your experience also changes with the model, prompt length, generated output, thinking effort, and service load. Look at time to a useful answer for your task; a quick first token followed by a very long response is not always the faster outcome.
For one person’s writing assistant, acceptable response time and whether it disrupts other applications may be enough to decide. For a shared service, consider simultaneous users, queued work, failures, and recovery. A single-user result does not establish capacity for a team.
The work you still own with either route
With the API, keep the key on a trusted server or in an appropriate secret store, not in a public page or shipped client-side code. Handle insufficient balance, timeouts, rate limits, and provider failures. Limit retries so that one failed task does not create an uncontrolled stream of requests. The provider runs the GPUs; it does not run your application’s budget or recovery plan.
With local inference, maintain the runtime and model files, keep enough disk and memory available, and decide who can access the service. For shared hosting, also plan authentication, logs, updates, backups of important configuration, and a way to recover after a failed update. Preserve a known working configuration before replacing it.
Local hosting offers useful version control: you can retain a checkpoint instead of moving as a hosted service changes. That control also leaves you responsible for evaluating updates and compatibility fixes. Keeping an old version forever is not automatically the best operational choice.
Choose by the job you need to finish
A developer adding summarization to an app
Start with the API if the data is approved for hosted processing. You can learn the integration, inspect actual token use, and understand demand before buying inference hardware. Flash is a sensible first candidate on price; use Pro when its documented capabilities and your task requirements justify considering the higher cost. Avoid choosing a larger model solely because its name sounds more capable.
A writer or researcher working offline
A small local model is worth considering when you need access without a connection and the computer can run it comfortably. Keep expectations tied to the task: rewriting a paragraph and analyzing an entire collection of documents are different workloads. Make sure file reading and retrieval also work locally, and keep the original sources available for checking the answer.
A team with restricted internal material
Start with the permitted data flow. If the material cannot leave your approved environment, a low API price does not resolve that restriction. An internal deployment may be appropriate, provided the model fits the task and someone owns the security and operations. If a third-party hosting route is considered instead, assess that provider’s terms and controls separately from DeepSeek’s direct service.
A service with sustained, predictable demand
Self-hosting deserves a closer financial review when you can keep suitable hardware busy and already have people to operate it. Include realistic idle time, redundancy, output quality, and maintenance. If demand is uncertain or highly uneven, a managed API lets you learn the workload without committing to fixed capacity.
When a hybrid setup is worth the extra work
A hybrid design can assign approved routine work to one route and keep restricted documents inside a local environment. It can also let you experiment locally while the existing application continues using a hosted service. The benefit must be concrete, because you now maintain two configurations and two sets of behavior.
Write the routing rule before adding a fallback. For instance, a task marked “local only” should stop or wait if its local model fails; it should not silently send the same document to a cloud model. Removing a name is not always enough to make sensitive text suitable for another destination.
A sensible first step for each route
For the API: choose the official service, sign in to the platform, create a key, and check the available balance. Keep the key private and start with one non-sensitive request. Confirm that you receive the expected output, then inspect usage and add error handling before connecting real users. Our DeepSeek API guide provides the Python and Node.js setup.
For local use: choose a runtime such as Ollama or LM Studio from its official site. Select a supported checkpoint that fits your machine, check its source and license, and download it. Start with a short conversation and modest context before loading a large document. Confirm which model is running and whether any cloud option is enabled. You should be able to identify the files, runtime, and data destinations rather than just recognize a familiar logo.
Only consider a shared or full-size deployment after that choice is clear. Serving engines such as vLLM and SGLang can be relevant for that stage, but they do not remove the need to size the hardware and support the selected architecture. A desktop setup guide and a production deployment plan answer different needs.
Frequently asked questions
Is running DeepSeek locally free?
Running downloaded weights can avoid a hosted model’s per-token charges, subject to the model and software licenses. You still provide the hardware, power, storage, and maintenance. On an existing computer, those additional costs may be small; a new GPU purchase changes the calculation.
Do I need a GPU for the DeepSeek API?
No. DeepSeek runs the hosted model. Your device or application sends requests over the network. A GPU becomes relevant when you run model inference yourself, and the requirement depends on the chosen model and runtime.
Can I run DeepSeek without internet access?
Yes, with a supported downloaded model and a fully local application. Obtain the model and required software first. Cloud models, web search, remote tools, and online document services still require connectivity. DeepSeek’s official hosted API does not work offline.
Is a local DeepSeek model automatically private?
No. Local inference changes where the model runs, but connected tools, application logs, backups, and shared access still matter. Check the complete workflow. A program installed on your computer can also be configured to use a cloud model.
Can I switch between the API and a local model later?
Often, if the application supports configurable endpoints and model names. Check request fields, context, images, tool calls, streaming, and output handling for the new server. Also reassess data permissions before changing a local task to a hosted route.
Will a small R1 model match the current hosted DeepSeek models?
You should not assume so. It is a different checkpoint with different size and training. It may be sufficient for your particular task, which is more useful than expecting identical answers across deployments. Compare the result you need, not the shared brand name.
Is using a third-party DeepSeek API the same as self-hosting?
No. If a provider operates the model and charges you for access, you are using its hosted service. Its model version, features, prices, and data terms can differ from DeepSeek’s direct API. Self-hosting means you operate the inference deployment, even if you rent the underlying machine.
Choose the simplest route that meets your constraints
If your data may be sent to a hosted service and you want to build something now, start with the API and use its actual usage figures to plan the next step. If offline access or control over the environment is essential, start with a local model sized for the hardware you have. Consider full-scale self-hosting when the model, workload, and operating responsibilities justify it.
Before spending more, write down three things: the task the model must complete, where its inputs are allowed to go, and the quality and response time you need. The right deployment is the one that meets those conditions at an acceptable total cost. That gives you a decision you can revisit as your workload changes.